Blog Menu G
Search
Categories
m
m

Category: 4GoodHosting

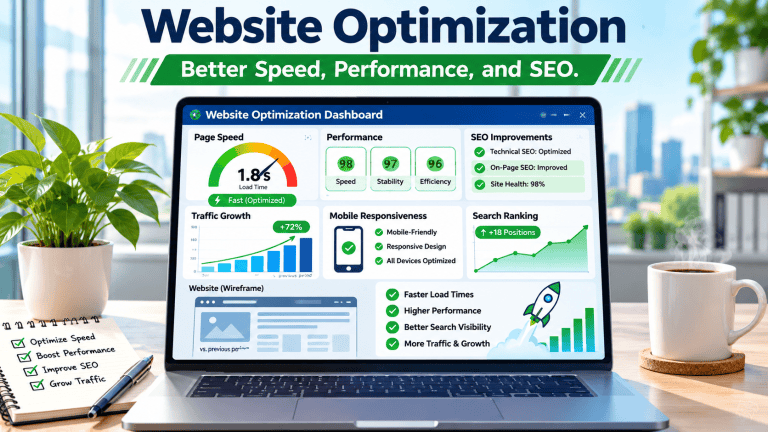
website optimization dashboard and growth 768x432

Friendly competition is fine in most instances, but there’s really no such thing if it’s competition in a business space. Especially if what’s at stake is your online business’ profitability versus having it going to your competitors. If you’re in eCommerce then you need to have your website serving as the primary engine for your success, and ideally your website is better than your competitors’ sites too. One area where it really ought to be better if your aim is to have maximum visibility for new customers is with its search engine optimization, or SEO as it usually is used as an acronym. And good SEO can definitely be included with website design. So yes your site can have good SEO right from the get-go, but what usually happens is that over time a site’s optimization needs to be revisited. Good SEO will by varying all the time based on the ever-changing algorithms of the search engines and that’s what it can be good to have a SEO audit for your site every several years or so. Often the folks you choose for website design in Toronto will be able to help you with that, or point your in the right direction to someone who really knows search engine optimization inside out. But it’s also something that you can get from you website hosting provider, and often for a much more agreeable price. That’s the case right here at 4GoodHosting, and over the course of 20+ years of being in this business we’ve definitely gained a rock solid understanding of what it takes to have a website reliably coming up on the first or second page of search engine results. That doesn’t apply to everyone here, but it certainly does for the SEO experts that we have on tap and ready to help eCommerce business owners with improving their site. There can be quite a spread of improvements that go into that, and it’s not just so simple as incorporating the right keywords at the right densities. If it were that simple then the fact that anyone and everyone can figure out how to use Google AdWords fairly quickly would...
You may find this interesting too.
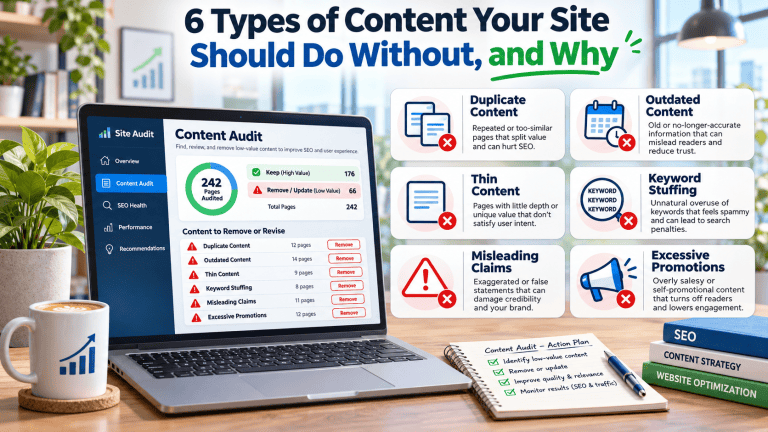
content audit six things to remove 768x432

More content isn't automatically a good thing. A site that publishes constantly but fills its pages with filler, duplication, or stale information is often worse off than one that publishes less but keeps every page genuinely useful — both for the people reading it and for how search engines evaluate it. The six categories below show up across sites of every size, usually added with good intentions, and each one quietly works against the site around it. 1. Thin Content That Doesn't Actually Answer Anything Thin content is a page that exists, technically answers a topic in its title, and says almost nothing once you read it: a few generic sentences, no real detail, nothing a reader couldn't have guessed before clicking. It shows up most often on pages created to fill out a template — a service page for every city a business claims to serve, a product description copied from a manufacturer's spec sheet with nothing added. Why it hurts: search engines don't index everything they crawl, and thin pages are one of the most common reasons they decline to. We cover exactly how that plays out — including the Search Console status that flags it — in why thin, duplicated pages quietly stop getting indexed. Beyond indexing, a reader who lands on a thin page and learns nothing leaves immediately, which is its own cost regardless of how the page ranks. What to do instead: write fewer pages and make each one genuinely answer the question it targets, with specific detail a reader couldn't get from a two-second glance. If a page can't say more than a sentence or two of substance, it usually shouldn't be its own page. 2. Duplicate or Near-Duplicate Content This takes a few common forms: the same paragraph pasted across a dozen location or service pages with only a city name swapped, a page copied wholesale from another site, or several pages on the same site quietly competing to answer the same question. Why it hurts: search engines index one version of duplicated content, not all of them, and when you haven't told them which version matters most, the one they pick...

You may find this interesting too.
canadian website modernization playbook 768x432

Most websites don't fail all at once. They erode. A plugin stops getting updated, a hero image balloons to four megabytes because nobody ever resized it, a contact form was wired up in 2019 and nobody has tested it since, and one day the site that used to load in two seconds is taking six. Nothing is technically “broken,” which is exactly why these problems survive so long — there's no error message forcing a decision, just a slow accumulation of friction that shows up in bounce rate, in support tickets, and eventually in rankings. A retrofit is the deliberate alternative to that slow decline, and to its opposite extreme: a full rebuild. Instead of tearing a site down and starting over, a retrofit treats the existing site as a structure worth keeping and upgrades it in place — the content, the backend, the hosting environment, the security posture — one load-bearing piece at a time. Done well, it's cheaper than a rebuild, faster to execute, and far less risky to search visibility, because the URLs, the internal link equity, and the content history that Google has already indexed stay intact. Done badly, a retrofit is just a rebuild with extra steps: changes made without a diagnostic baseline, a CMS migration rushed ahead of a security audit, a new theme installed on top of hosting infrastructure that was already the actual bottleneck. This guide lays out a sequenced, evidence-based approach to retrofitting a website — what to audit first, which fixes compound on each other, where the hosting layer does more work than people expect, and how Canadian businesses in particular should think about data residency and latency while they're at it. None of this requires a single enormous project with one launch date. The approach below breaks a retrofit into phases that can each be scoped, budgeted, and measured on their own, so a business can start with whichever phase is causing the most immediate pain — usually hosting and performance — and keep going as budget and priorities allow, rather than waiting for the ideal moment to fund the whole thing at once. What a Website Retrofit Actually...

You may find this interesting too.
4gh blog post pic.webp

Chrome ships browser updates constantly, and most of them never reach a business owner's radar — a new menu item, a redesigned settings page, a feature nobody outside Chromium's own team will notice. Every so often, though, an update changes something that actually touches how a website performs for mobile visitors, and two recent Chrome for Android changes fall squarely into that category. Neither one is a redesign or a new button. Both are changes to how the browser decides when to load content and how aggressively it tries to get ahead of what a visitor is about to do next — and both quietly shift more of the responsibility for a fast mobile experience onto the server the site is running on. That's the throughline worth paying attention to: as Chrome gets better at deciding what not to load yet and at guessing what to load early, the gap between a fast host and a slow one becomes more visible, not less. This isn't a full Core Web Vitals primer — that ground is covered elsewhere. This is specifically about these two updates, what they do, and what to actually check on the hosting side so a site benefits from them instead of getting caught out by them. Two Updates, One Pattern The first update, shipped in Chrome 148 (stable since early May 2026), adds native lazy-loading support for video and audio elements — the same deferred-loading behaviour Chrome has long supported for images, now extended to media. The second is the continued rollout of Speculation Rules–based prefetching and prerendering on Android, which lets Chrome request a page's content before a visitor has even tapped the link, based on signals that the tap is likely coming. Both features are, on paper, pure wins for the visitor: less data pulled down for content they haven't scrolled to yet, and pages that feel instant because they were already loading before the tap landed. The pattern underneath both of them is what matters for a site owner: Chrome is increasingly good at not asking for things until it needs them, and increasingly good at asking for things slightly before it needs them....

You may find this interesting too.
4gh blog post pic.webp
reading time Reading Time: 20 minutes

"Sovereign cloud" has moved quickly from a policy term to a sales term. Governments use it when they set rules for sensitive data. Large technology companies use it to market new regional offerings. Procurement documents ask for it without always defining it. For a Canadian organization trying to decide whether it needs one, the word can mean almost anything. Underneath the marketing is a real and practical question: who can reach your data, under which country's laws, and who is actually in control of the systems that hold it? Answering that question well matters more than the label. A sovereign cloud is cloud infrastructure designed so that data, operations and control stay under the laws of a single country and out of reach of foreign jurisdictions. In practice, that means data is stored in the country, the systems are operated by locally based entities and staff, and the customer controls the encryption keys. Sovereignty is a spectrum, and most offerings provide some of these protections rather than all of them. This guide explains what a sovereign cloud is, how it differs from data residency, the three layers of sovereignty, why the idea has become a priority, how Canadian rules apply, who actually needs it, and how to evaluate a provider's sovereignty claims. What Is a Sovereign Cloud? A sovereign cloud combines three assurances: the data stays in a defined country, the people and companies operating the service answer only to that country's laws, and the customer, rather than the provider, controls access to the data through encryption and policy. The goal is to make sure that no foreign government, court or company can compel access to the data, or disrupt the service, without going through the country's own legal system. The term is used loosely, so it helps to separate it from two related ideas. Term What it means What it doesn't guarantee Data residency Data is stored in a specific country or region That foreign laws can't reach the provider holding it Data localization A law or policy requires certain data to stay in the country Anything about who operates the systems or holds the keys Data sovereignty Data...

You may find this interesting too.
retiring zombie servers in blue light 768x432
reading time Reading Time: 20 minutes

Somewhere in most organizations there's a server nobody remembers. It might be a tower in a storage closet that once ran a project database, a virtual machine left over from a migration, a cloud instance a developer spun up for a test, or a hosting account still renewing for a website that was replaced years ago. It's switched on, it's costing money, and nobody is looking after it. These are zombie servers. They do no useful work, but they keep drawing power, consuming budget and, most dangerously, sitting unpatched on the network where an attacker might find them before you do. A zombie server is a server that's still running but no longer does useful work. It may be physical, virtual, in the cloud or a forgotten hosting account. Zombie servers waste energy, hardware, licences and cloud spending, and because nobody maintains them, they become unpatched security risks. Finding them takes an inventory and usage data; retiring them safely takes a careful decommissioning process. This guide explains what zombie servers are, how they appear, what they really cost, why they're a security problem, how to find them, how to retire them safely, and how to stop new ones from appearing. What Is a Zombie Server? A zombie server, sometimes called a comatose or orphaned server, is any server that's powered on and connected but no longer provides a service anyone needs. The term covers more than physical machines. Zombies appear wherever computing can be created and forgotten. Type What it looks like Typical origin Physical server A machine in a closet or rack with no current purpose Replaced by a newer system but never switched off Virtual machine A VM on a host that nobody logs into Created for a project, test or migration Cloud instance A cloud server still billing every hour Spun up for development or a short project Hosting account A plan still renewing for a site nobody uses A rebrand, a closed campaign or a departed staff member Website or application An old site still online on its original hosting A redesign launched elsewhere; the old site left running DNS record A record pointing to a...

You may find this interesting too.
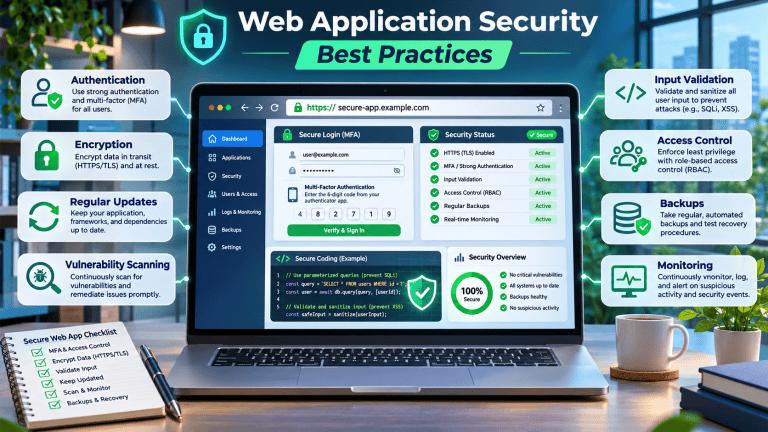
web application security best practices 768x432

A web application fails securely in layers, and it's worth separating two things that get talked about as one: how your server and hosting environment are configured, and how the application itself — its code, its logic, the data it handles — is built. A hardened server cannot fix a SQL injection flaw in your own code, and secure code running on an unpatched, unmonitored server is still exposed. This guide focuses on the application layer — the practices a developer, site owner, or technical lead can act on directly — and points to dedicated guides on this site for the server and certificate side of the picture rather than repeating them. None of this amounts to a guarantee. No set of practices makes a web application immune to every attack, and anyone promising that is overselling. What a disciplined set of practices does is close the common, well-understood paths attackers actually use, which removes the overwhelming majority of real-world risk at a reasonable cost. Start From a Recognized Framework Rather than building a security checklist from scratch, most teams are better served starting from OWASP, a nonprofit foundation that maintains the most widely referenced web application security resources. The OWASP Top 10 names the categories of risk responsible for the large majority of real-world web application breaches — things like broken access control, cryptographic failures, injection flaws, security misconfiguration, and vulnerable or outdated components — and it's revised periodically as the threat landscape shifts, so it's worth checking you're looking at the current edition rather than one a few years old. For teams that want something more granular than a top-10 list, the OWASP Application Security Verification Standard (ASVS) breaks those categories down into specific, checkable requirements at different levels of rigor, which makes it useful as an actual audit checklist rather than just a reading list. Our own Cybersecurity: 15 Types of Web Attacks to Watch Out For covers how these attacks actually work in detail — SQL injection, cross-site scripting, CSRF, session hijacking and the rest — so this guide won't re-explain the mechanics. What follows is organized the other way around: by the defensive practice, not...

You may find this interesting too.
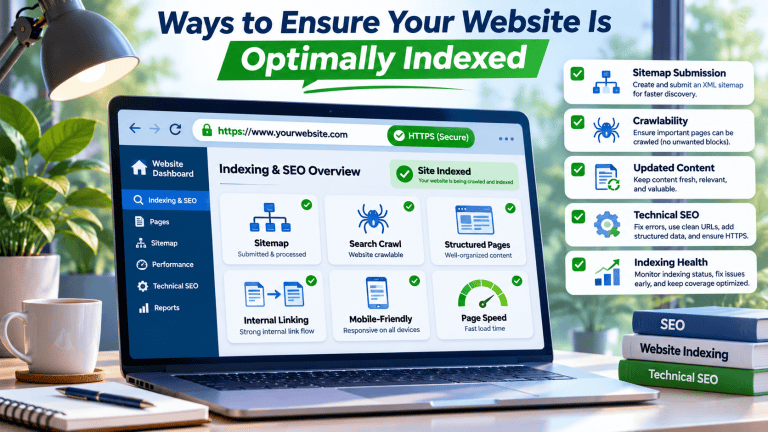
optimally indexed seo workspace 768x432
reading time Reading Time: 17 minutes

A site going live is not the same thing as a site being indexed. Plenty of website owners publish a page, check that it loads in a browser, and assume Google will simply find it. Most of the time that happens — eventually. But "eventually" can mean weeks, and for a meaningful share of pages on the open web it never happens at all. Google's own guidance is direct about this: not every page that is crawled gets indexed, and not every page that is indexed stays indexed if something changes. This matters because indexing is the gate everything else passes through. A page cannot rank, cannot appear in Google's AI-generated answers, and cannot send a single click from organic search if it isn't in the index. Content quality, backlinks, and keyword targeting are all wasted effort on a page Google has chosen not to index, or hasn't found at all. This guide works through the practical, controllable reasons pages fail to get indexed, in roughly the order they're worth checking, and ends with a short checklist you can run against your own site. What "Indexed" Actually Means Google's documentation separates the process into three distinct stages, and the distinction matters because a problem at one stage looks completely different from a problem at another. Crawling — Googlebot discovers a URL and requests it. Indexing — Google processes what it fetched and, if the page qualifies, stores it in the index that search results are drawn from. Ranking — for a given query, Google decides where an indexed page appears, if it appears at all. A page can be crawled without being indexed, and it can be indexed without ranking anywhere useful. Each stage has its own failure modes, which is why "my page isn't showing up in Google" is really three different diagnostic questions wearing one symptom. Google Search Console's Page Indexing report (sometimes still called the Index Coverage report) is built around this distinction. It groups every known URL on your property into named statuses. A few of the ones worth recognizing on sight: Status (as Search Console labels it) What it generally means Submitted and indexed The...

You may find this interesting too.
canadian domain extensions explained 768x432

Choosing a domain name used to mean choosing between .com and, for Canadian businesses, .ca. Today there are hundreds of other endings available, from .shop and .tech to .online, .app and .law. Some are useful. Some are mostly marketing. A few carry risks that aren't obvious when you register them. The part of a domain after the final dot is called its extension, or top-level domain. It affects how customers read your address, how search engines interpret it, how email filters treat it, what it costs to renew, and in some cases how your website must be configured. It's worth understanding before you register one. A domain extension, or top-level domain (TLD), is the last part of a domain name, such as .ca, .com or .shop. There are three main kinds: country-code extensions like .ca, generic extensions like .com and .org, and newer generic extensions introduced since 2012 like .shop and .tech. For most Canadian businesses, .ca and .com remain the safest main choices, with newer extensions best used for specific campaigns or products. This guide explains the types of domain extensions, how the newer ones came about, how customers, search engines and email systems treat them, the costs and technical requirements to watch for, and when a newer extension makes sense for a Canadian business. The Main Types of Domain Extensions Every domain extension is managed by a registry, which sets the rules for who can register names and at what wholesale price. Registrars then sell those names to the public. The extensions fall into a few broad groups. Type Examples Who can register Notes Country-code (ccTLD) .ca, .uk, .de, .fr Usually limited to people or organizations connected to the country, depending on the registry Signals a national connection; .ca is managed by CIRA under Canadian presence rules Original generic (gTLD) .com, .net, .org Anyone .com is the default most people type; .org is common for non-profits but open to all Sponsored or restricted .gov, .edu, .int Restricted to specific types of organization Not available to ordinary businesses Newer generic (new gTLD) .shop, .tech, .online, .app, .law, .design Usually anyone; some have eligibility rules Introduced through ICANN's new gTLD...

You may find this interesting too.
ransomware protection workspace 768x432

Ransomware used to be thought of as a home-computer problem: a pop-up demanding payment to unlock your family photos. That picture is long out of date. Today's ransomware is run by organized groups that target businesses deliberately. They break into networks, look for the systems and backups that matter most, steal data, and then encrypt everything they can reach. The ransom note arrives only once the damage is done. Small businesses are squarely in the target range. They hold valuable data, depend on a handful of critical systems, and rarely have dedicated security staff. The good news is that most successful attacks exploit a short list of weaknesses, and most of those can be fixed without a large budget. Ransomware is malicious software that encrypts an organization's files and systems so they can't be used, then demands payment for a decryption key. Most modern attacks also steal data first and threaten to publish it, so effective ransomware protection combines prevention, backups that attackers can't reach, and a tested plan for responding and recovering. This guide to ransomware protection explains how ransomware works today, how attackers get in, the controls that prevent most attacks, how to build backups that survive one, how to protect websites and servers, what to do if you're hit, and the reporting obligations Canadian organizations need to know. What Is Ransomware? Ransomware is a type of malware designed to extort money. Once it runs on a system, it encrypts files with a key the attacker controls. Documents, databases, images and sometimes entire servers become unreadable. A ransom note explains how to pay, usually in cryptocurrency, in exchange for a tool that promises to reverse the encryption. How ransomware has changed Early ransomware strains, such as those that spread widely around 2013 and 2014, were mostly opportunistic. They arrived in email attachments, encrypted whatever a single computer and its mapped network drives could reach, and demanded a modest payment. Modern ransomware operations work very differently. Then Now Opportunistic, mass-emailed infections Targeted intrusions, often by groups that buy access to a victim's network Encrypted files on one PC and its mapped drives Spreads across servers, virtual machines, cloud storage...

You may find this interesting too.
ai powered linux workspace 768x432

For years, headlines about artificial intelligence have followed the same pattern: models are being trained faster, on more hardware, than ever before. The headlines are right. Epoch AI, a research group that tracks the computing power used to train notable AI models, estimates that training compute has been growing by roughly four to five times every year. That growth happens in purpose-built facilities filled with specialized accelerators, run by a handful of very large organizations. None of it happens on a small business's hosting plan. And yet the same trend has quietly changed what a small business can do with an ordinary server. As the frontier races ahead, capable models are also getting much smaller. Stanford's AI Index 2025 reports that in 2022, the smallest model to score above 60% on a widely used knowledge benchmark had 540 billion parameters; by 2024, a model with 3.8 billion parameters cleared the same bar. That is a 142-fold reduction in two years. Smaller models, cheaper AI services and mature open-source tools mean that AI hosting for small business is no longer a contradiction. A retailer can add semantic product search. A property manager can make ten years of maintenance notes searchable in plain language. An accountant can run a nightly forecasting job. Some of that work belongs on external AI services; some of it runs comfortably on a Linux virtual private server; a little of it genuinely needs more. This guide sorts those workloads out. It explains the difference between training and inference, the four kinds of AI work small businesses actually run, how to size CPU, memory, storage and GPU for each, how to run AI alongside a website without slowing it down, and where your data goes when you choose web hosting in Canada for AI features. It deals with AI that runs on your server. For the other side of the coin, the load that AI crawlers now put on your hosting, see our separate guide. What does "AI hosting" mean for a small business? AI hosting, for a small business, means running the parts of an AI feature that live on your own infrastructure: the application that calls...

You may find this interesting too.
1ce1ce4e186cbe4bfd5348f461abdf44951f024ce753041d15f8702fc1b2c24f 768x432
reading time Reading Time: 8 minutes

A website is never going to have elbows, or knees, ankles, or wrists for that matter. No need for them to be concerned about getting arthritis when they get old either. But that doesn’t mean some websites are going to need more ‘elbow room’, as the expression goes. When a website is on shared web hosting it may be that the fact it’s sharing server resources with other sites means that it doesn’t have the space it needs to get wide as need be. That primarily refers to page loading and website page load speeds, and that’s why there is more elbow room to be had with Canada Linux VPS hosting. The websites that will most immediately benefit from this type of web hosting are going to be business websites, and that will be for obvious reasons. It’s not that a personal website will never have a traffic spike where numerous site visitors are all making the server request to enter the site at the same time, but it’s probably going to an extremely rare instance. And there isn’t going to be any measure of negative ramifications if that does happen. For a business website, though, a site that can’t open for even one or two of those visitors may mean lost revenue if it’s working as an eCommerce website. Windows VPS hosting will provide the same space and resource-availability assurances for Windows-built websites, and for nearly any business owner the higher yearly-plan rate for Linux VPS hosting or Windows is going to be an entirely agreeable part of their operating budget considering what their website does for the visibility of their business. Plus allowing customers to make purchases without having to come in to the physical storefront - if there even is one. Many online businesses only have their eCommerce site serving as the only location where products can be purchased, and if that’s your business type too and you’re in a competitive market where margins can be thin then you need to have your website readily available 24/7 and for anyone and everyone who chooses to enter the site and make their own choices about whether you’ve got...

You may find this interesting too.
4gh blog post pic.webp

A domain name is one of the few business decisions that's cheap to make and expensive to change. Registering one takes a few minutes. Changing it later means reprinting signs and vehicles, updating every listing and profile, moving email addresses, setting up redirects and accepting a dip in search visibility while everything settles. Small businesses that rush the choice often live with an awkward name for years because switching feels harder than putting up with it. For a Canadian small business, the decision has a few extra layers: whether to use .ca, .com or both, who is eligible for a .ca, how bilingual names work, and how to keep the domain legally and practically under your control. A good small-business domain name is short, easy to spell when heard aloud, clearly connected to your business name, free of trademark conflicts, and registered in your business's own name. For businesses serving Canadians, a .ca domain signals a Canadian presence, and registering the matching .com as well protects the name. This guide explains how Canadian domain names work, how to decide between .ca and .com, the principles behind a strong name, what actually matters for search, the legal checks to run first, and how to register, protect and connect your domain once you've chosen it. What Is a Canadian Domain Name? A Canadian domain name usually means a name ending in .ca, Canada's country-code top-level domain. Since 2000, .ca has been managed by the Canadian Internet Registration Authority (CIRA), a not-for-profit organization. CIRA doesn't sell domains directly to the public. You register a .ca through a CIRA-certified registrar, which is often a hosting or domain company, and the registrar submits the registration to CIRA on your behalf. Unlike .com, which anyone in the world can register, .ca has eligibility rules. CIRA's Canadian Presence Requirements limit .ca registrations to people and organizations with a real connection to Canada. Who can register a .ca The Canadian Presence Requirements cover a range of registrant types. For small businesses, the relevant ones are usually: Registrant type Typical small-business example Canadian citizen or permanent resident A sole proprietor registering in their own name Corporation incorporated under federal,...

You may find this interesting too.
No related posts found.
1111111111111111111 768x402
reading time Reading Time: 26 minutes

Most people who have bought an NFT believe they own a picture, a song or a ticket. In most cases, what they own is a line in a public ledger that says a particular token belongs to their wallet. That token usually holds a web address. The address leads to a small text file, and the text file leads to the picture. The picture itself sits on a server somewhere, and somebody has to keep that server running. That chain of pointers is the part of the NFT story that rarely gets explained, and it's where NFTs meet ordinary web hosting. When the server goes offline, the domain expires or the files are never backed up, the token survives but points to nothing. An NFT (non-fungible token) is a unique token recorded on a blockchain that proves which wallet holds a specific entry in a smart contract. The token normally stores a link to a metadata file describing the item, and that file links to the media. The image, video or document is usually stored somewhere else, not inside the token. This guide explains what an NFT is, what it actually records, and where NFT files are stored in practice. It covers how NFTs end up pointing to nothing, what buying one does and doesn't give you, and how to check one before you buy or issue it. It finishes with the business uses that outlasted the hype, and what it takes to host NFT media and metadata properly. What Is an NFT? An NFT is a token created by a smart contract, a small program running on a blockchain. The contract keeps a list of token IDs and the wallet address that holds each one. When an NFT is sold or transferred, the contract updates that list, and every node on the network records the change. "Non-fungible" means each token is distinct. One Canadian dollar is interchangeable with any other, which makes it fungible. A concert seat is not: row F, seat 12 is a different thing from row F, seat 13. An NFT works like the seat. Each token ID is unique within its contract, so the pairing...

You may find this interesting too.
featured image 1200×628@1x 1 768x402

Open the Wi-Fi list on your phone in almost any office lobby and you will probably see a network nobody set up on purpose. It might be called DIRECT-4F-Printer-2ndFloor or DIRECT-xy-Boardroom. It doesn't appear on the network diagram and IT never configured it, yet it is broadcasting from a device a few metres from the accounting team. That network is Wi-Fi Direct at work. It's the reason a topic that sounds like gadget trivia belongs in a business conversation about infrastructure. Wi-Fi Direct is a Wi-Fi Alliance standard that lets two or more devices connect to each other over ordinary Wi-Fi radios without a router, access point or internet connection. One device takes on the job an access point would normally do. The others join it, and data moves directly between them at Wi-Fi speeds. The convenience is real. A guest can print from their phone, a laptop can mirror to a meeting-room display, and a large video can move between two phones in seconds. The same design also creates small, self-managed networks that sit outside the controls an organization relies on. They have no firewall policy, no central logging and no backup, and they pair using methods that were never built for hostile environments. This guide explains what Wi-Fi Direct is and how a connection actually forms. It compares Wi-Fi Direct with Bluetooth and newer peer-to-peer options, shows where it creates security exposure in an office, and sets out how to lock it down without breaking printing. It ends with the point where business files should stop moving device to device and start living on a properly hosted server. What Is Wi-Fi Direct? Wi-Fi Direct is a peer-to-peer mode of Wi-Fi. Standard Wi-Fi works like a hub with spokes: every laptop, phone and printer connects to an access point, and the access point moves traffic between them and out to the internet. Wi-Fi Direct removes the hub. Two devices that support it can find each other, agree on which one is in charge, set up an encrypted link and exchange data, with no router involved. The Wi-Fi Alliance, the industry body that certifies Wi-Fi products, launched its Wi-Fi Direct...

You may find this interesting too.
toronto data center at dusk 768x432

Most conversations about server clustering start with a promise: link several servers together and your application becomes faster, more reliable and ready for any amount of traffic. Part of that is true. A well-designed cluster can absorb traffic that would flatten a single machine, keep serving visitors while a server fails, and let your team patch hardware in the middle of a business day without anyone noticing. What the promise leaves out is that a cluster does not make an individual request faster. In some designs it makes requests slower, because servers now have to agree with each other before they answer. A cluster also adds new ways to fail, new costs and a level of operational discipline that many teams underestimate until the first time a failover does not behave the way the diagram said it would. This guide takes the more useful view. It explains the main kinds of server clusters, what each one actually improves, where the hidden costs sit, and how to decide between one larger server and several smaller ones. It also covers a question the generic guides skip: how Canada's geography and privacy rules shape cluster design when your data centres sit thousands of kilometres apart. In short: Server clustering links two or more servers so they work as one service, either sharing incoming load, standing by to take over if one fails, or both. Clustering mainly improves capacity (how many requests you can handle at once) and availability (whether you stay online when something breaks). It does not reduce the time a single request takes, and replication between servers can add delay. Clusters are worth their cost when one server can no longer carry the load, or when downtime costs more than the extra hardware and operational effort. What server clustering means, and the four kinds people confuse "Cluster" is used loosely enough that two people can agree they need one while picturing completely different systems. It helps to separate four designs, because each solves a different problem. Load-balanced clusters A load balancer sits in front of several identical application servers and spreads incoming requests among them. If one server is busy or...

You may find this interesting too.
global network performance dashboard 768x432
reading time Reading Time: 6 minutes

Every time a web page displays on your device there’s a very uniform process that makes that happen. Many people won’t exactly know what’s involved, but to explain it simply there’s a request made to the web hosting provider’s server and the response is to make the page available to you when you click on it. There’s more technicality to it and we could go on at length about how web hosting works. But instead what we’ll do is explain how web pages load faster and more reliably when the web host’s server is located nearby to where the site visitor is making the request. Linux web hosting tends to be the best choice for site functionality, but having your site on a server that’s close by adds to that suitability. This is especially relevant if your website is for your business and you’re relying on it to push the growth and profitability of what you’re doing. An eCommerce website needs to have the homepage loading quickly for visitors, and page load speeds are a factor in how well the site does with SEO and coming up higher in search engine result pages. Most good Canadian web hosting provers will have data centers on both sides of the country, and that means speedy server responses when site visitors are primarily located in Ontario or British Columbia. Toronto and Vancouver are two of the most densely populated cities in Canada and it makes sense that many of those small eCommerce businesses are going to have the bulk of their customers in those areas. If you’re the person behind that small business and your website is an integral contributor to your success then it’s going to best to have your site on a more local server, and that’s something that we can make available to you at 4GoodHosting. So what we’ll do with this week’s blog entry is go over the role of server location in website performance and SEO and why the ultimate Linux hosting with cPanel is probably going to be the best option for you if you’re going to be more proactive in having an optimized website that’s best...

You may find this interesting too.
cyber ai speed surge 768x432

A few years ago, asking an AI model a question was slow and expensive enough that most businesses treated it as a novelty. That changed quickly. Stanford's 2025 AI Index estimated that the cost of running a model at roughly GPT-3.5-level performance fell from about US$20 per million tokens in November 2022 to about US$0.07 by October 2024, a drop of more than 280-fold in under two years. When something becomes that much cheaper and faster, it ends up everywhere, including on your website. Most commentary on faster AI focuses on the people using chat tools. Far less attention goes to the other end of the connection. Every AI answer that cites a page, every model refreshed with new training data, and every agent that checks a price or reads a returns policy on someone's behalf starts with a machine requesting a URL from a server. More and more often, that server is yours. The scale is no longer marginal. The 2026 edition of the Thales Imperva Bad Bot Report, covering full-year 2025, found that automated traffic made up about 53% of web traffic, up from 51% the year before, leaving human visitors at roughly 47%. Not all of that automation is AI, and not all of it is harmful. The direction, though, is unmistakable: a growing share of the requests your site answers come from software rather than people. That changes the question site owners should be asking. It used to be enough to ask whether a page loads quickly for a visitor in Halifax or Kelowna. Now the question is whether your hosting can absorb a steady background load of crawlers, fetchers and agents and still respond quickly to humans, to search engines, and to the AI systems deciding whether your content gets cited at all. This guide explains what has changed, what AI crawler traffic actually costs a website, how it connects to search visibility and indexing, and what to look for in a hosting environment that now has to serve both audiences. What is AI crawler traffic? AI crawler traffic is the portion of a website's requests that comes from automated systems collecting or retrieving content...

You may find this interesting too.
focused developer in a modern tech workspace 768x432

Anyone who makes all the effort required to write and assemble an online blog entry each week is going to believe that’s there’s considerable value in what they have to say. The subject matter will vary, but the majority of times if you build up an online readership and people start following your blog then you’re doing well with sharing good information via your content. There’s real value in having those followers building up too, and especially if you’re aiming to monetize your blog in the way so many bloggers are trying to do. You’ve got to have good quality content there consistently, and a lot of the time it will be best to be on affordable web hosting platforms. The best fit for affordability is usually going to be Linux shared hosting. At least for blogs that are created and maintained as part of a personal venture of any sort. For these folks their blogs are usually very simply laid out and it doesn’t require much in the way of available bandwidth for them to load quickly, and it’s not like there is ever going to be a surge of visitors looking to all ready the blog at the same time anyways. So the fact that it’s suitably reliable for their smaller website and the shared hosting is the least expensive options is going to be the foremost reason why most bloggers will go with this type of web hosting. The ultimate Linux hosting with cPanel is going to add to the appeal if they’re signed up with us here at 4GoodHosting. With cPanel controls it’s especially easy to be your own small-scale webmaster and make strategic reorientations with your blogger website to make it better. But we can imagine that most of these bloggers will be just fine with their basic site on a shared hosting server just as it is. Most websites are built with site architecture that fits best with Linux hosting and that means optimized performance, so it’s unlikely you’ll be doing much with the controls as it is. So what we’ll do with this week’s entry for OUR blog here is to look at...

You may find this interesting too.
chatgpt 35 768x432.webp
reading time Reading Time: 39 minutes

Most advice about increasing online sales is written for nowhere in particular. Improve your product photography. Write better email subject lines. Post consistently. Reduce friction at checkout. It is not wrong, exactly, and it is also the same list you would get in Manchester or Melbourne. What it leaves out is everything that is actually specific to operating from here — the two separate sales tax systems you have to run simultaneously, the municipal licensing that fragments the moment you serve more than one city, the question of which privacy statute governs your customer list, and a set of operational realities that come from sitting three hours behind your largest domestic market. This guide is about that layer. It assumes you have already read the general advice and want the part that applies because you are in Vancouver. Some of it is tax, some is legal, some is infrastructure, and one item has a deadline nineteen days from the date this was written. Scope and a necessary disclaimerTax and licensing rules change, thresholds get adjusted, and the right answer frequently depends on facts specific to your business. Everything here is general information, not tax or legal advice, and it is written as of September 2026. Verify anything consequential against the current guidance on gov.bc.ca, vancouver.ca or with your accountant before acting on it. The cost of getting sales tax registration wrong falls on the seller, not on the customer. What is actually different about operating from Vancouver Four things, and the first two catch people repeatedly. You run two sales tax systems, not one British Columbia does not have harmonised sales tax. You collect federal GST at five percent and provincial PST at seven percent as two separate taxes, with different rules about what is taxable, different registration thresholds, different filing, and — critically — different recoverability. GST paid on business inputs is generally recoverable through input tax credits. PST paid on business inputs generally is not. That second point is the one that changes decisions rather than just paperwork. In an HST province, tax on your business purchases washes out. Here, PST on the things you buy to run...

You may find this interesting too.
On This Page G
Explore 4GOODHOSTING
Copyright © 2026 4GoodHosting. All Rights Reserved.
.CA by CIRA
+1 866 708 4678