

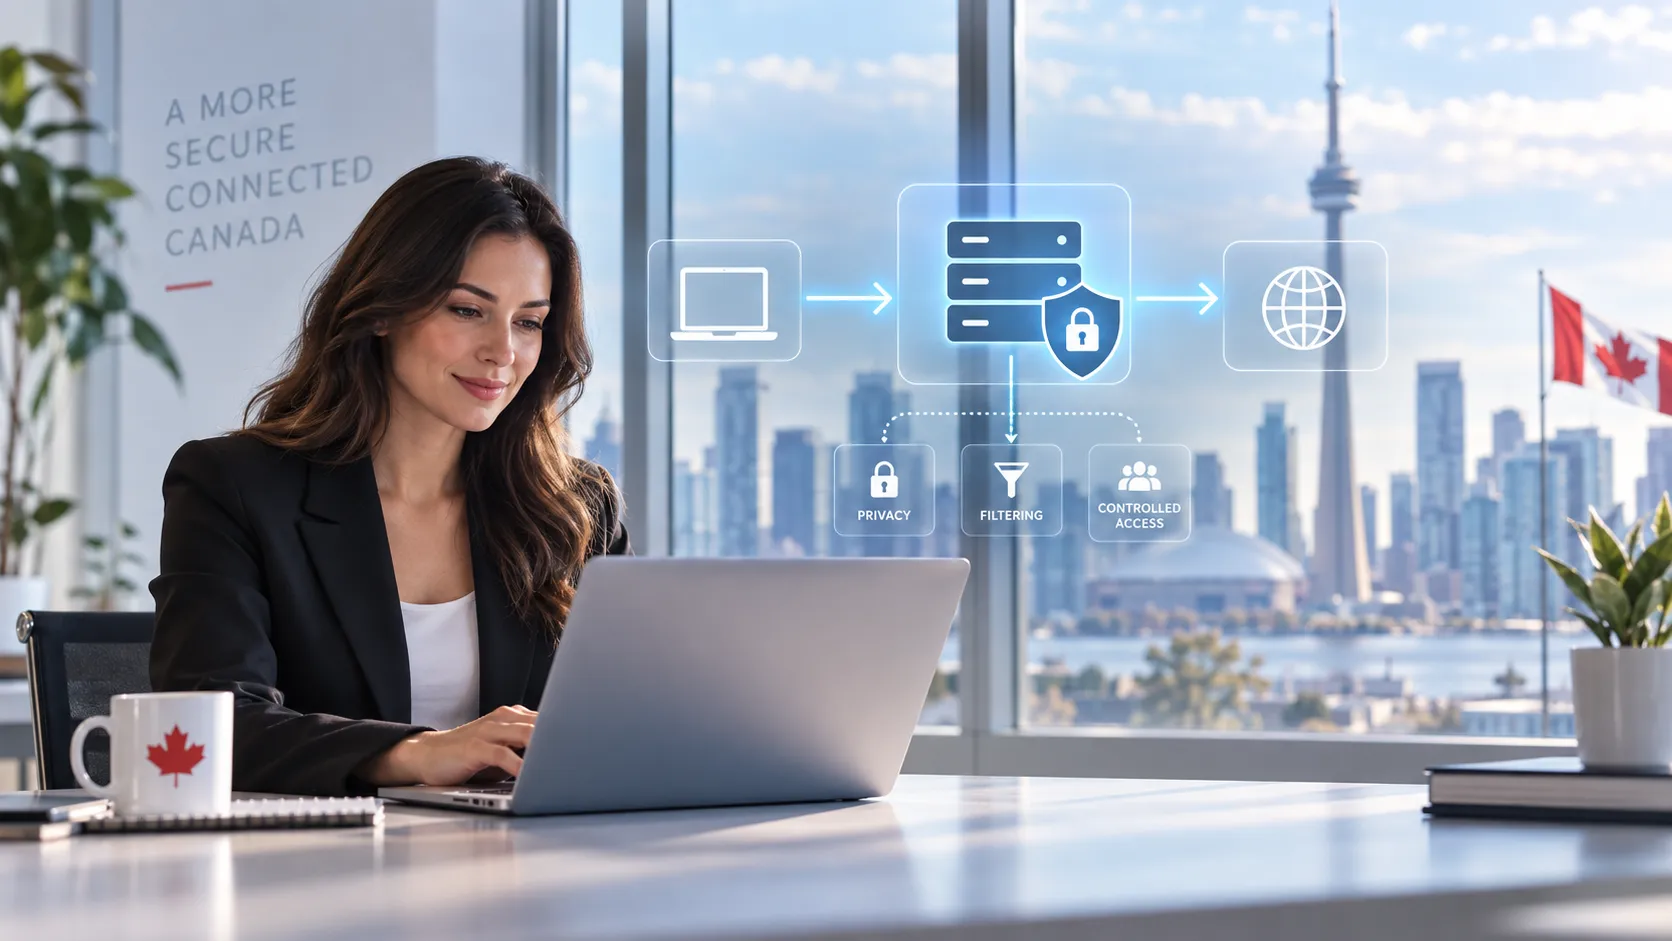
 A proxy server is a computer that makes requests on behalf of something else.
That is the whole idea, and everything else is detail. The reason proxies confuse people is not that the concept is difficult. It is that one word has been stretched to cover several genuinely different technologies that happen to share that one behaviour. The software filtering web traffic on an office network, the service sitting in front of a busy website distributing traffic across servers, the thing someone buys to scrape product prices, and the layer terminating encryption at the edge of a content network are all called proxies. They do not do similar jobs.
Most explanations of proxy servers make this worse rather than better. They list types without explaining what distinguishes them, they repeat the claim that a proxy encrypts your traffic (which is usually false), and they treat proxies and VPNs as near-synonyms (which they are not). By the end you know more words and no more mechanics.
This guide takes the opposite approach. It explains what a proxy actually does at the level of the request, distinguishes the two fundamental directions a proxy can face, works through the types properly, is specific about what happens to encrypted traffic, and is honest about what proxies can and cannot protect. It also covers the parts that matter for a Canadian business in particular, including where a proxy sits relative to your data and what that means for the privacy commitments you may have made to your clients.
The definition, and the request path
A proxy server is an intermediary that receives a network request, forwards it to its destination on the requester's behalf, receives the response, and passes that response back. The two endpoints communicate through it rather than directly with each other.
Walk through what happens without one first. You type an address into your browser. Your device resolves the hostname to an IP address, opens a connection to that address, sends an HTTP request, and receives a response. The web server sees your IP address, because your device is the thing talking to it.
Now insert a proxy. Your browser is configured to send requests to the proxy instead of to the destination. So:
- Your browser opens a connection to the proxy and sends the request, including the destination it wants.
- The proxy examines the request. Depending on configuration it may allow it, block it, log it, modify it, or answer it directly from a cache without contacting the destination at all.
- If it proceeds, the proxy opens its own connection to the destination server and issues the request.
- The destination server responds to the proxy. From the server's point of view, the proxy is the client. The IP address it sees and logs is the proxy's.
- The proxy passes the response back to your browser, again with the option to inspect, modify, cache, or filter it along the way.
Three consequences fall out of that sequence, and they explain nearly every use of proxies:
- The destination does not see the original requester. This is the basis of every anonymity and IP-masking use.
- A single point exists where all traffic can be observed and controlled. This is the basis of every filtering, logging, monitoring, and security use.
- Responses can be stored and reused. This is the basis of every caching and performance use.
Notice what is not on that list. Nothing about encryption. A proxy does not inherently encrypt anything. Whether your traffic is encrypted depends on whether you are using HTTPS, which is a separate matter from whether a proxy is involved. This misconception is widespread enough that it gets its own section later.
What a proxy is not
Before going further it is worth clearing away the things proxies get confused with, because the confusion causes real mistakes in purchasing and architecture decisions.
| Technology | What it actually does | How it differs from a proxy |
| VPN | Creates an encrypted tunnel at the network layer, carrying all traffic from a device or network | Operates below the application layer, so it covers every application rather than a configured few. It encrypts by definition; most proxies do not |
| NAT | Rewrites addresses so many devices share one public IP | Purely address translation. It does not understand or inspect the traffic, cannot filter by content, and cannot cache |
| Firewall | Permits or denies traffic against a rule set | Decides whether traffic passes. A proxy carries the traffic itself and can modify it. Many products do both |
| Load balancer | Distributes connections across several servers | A subset of what a reverse proxy does. Every load balancer is proxying; not every reverse proxy balances load |
| CDN | A geographically distributed network of caching servers | Effectively a large fleet of reverse proxies with caching, operated as a service |
| Gateway | A general term for a node joining two networks | Broader and vaguer. A proxy is one specific kind of gateway |
| API gateway | Manages, authenticates and routes API traffic | A specialised reverse proxy with authentication, rate limiting and request transformation built in |
Proxy versus VPN, since this is the common one
The distinction is about which layer the redirection happens at, and it has practical consequences.
A proxy is generally configured per application or per protocol. You set your browser to use a proxy and your browser's traffic goes through it. Your email client, your accounting software, and your operating system's update service carry on as before. That is sometimes exactly what you want, and sometimes a serious gap, because the thing you were trying to shield may not be the browser.
A VPN operates at the network layer. The tunnel is established by the operating system and every packet leaving the device travels through it. It also encrypts that traffic between the device and the VPN endpoint, which is not a property of proxies generally.
So a proxy is a narrower, more surgical tool. It is better suited to selective routing, application-specific filtering, caching, and any situation where you want a controllable inspection point. A VPN is broader and heavier.
One shared limitation deserves emphasis, because it applies to both and is often glossed over: whoever operates the intermediary can see what passes through it, to the extent it is not end-to-end encrypted. Routing your traffic through someone else's server does not make it private. It moves the party who can observe it. That is fine when you control or trust the operator, and a genuine risk when you do not.
The fundamental distinction: which side is the proxy working for?
Almost all of the confusion around proxies dissolves once you grasp one distinction. Proxies come in two directions, defined by whose behalf they act on.
Forward proxies act for clients
A forward proxy sits in front of clients and makes requests outward on their behalf. The client knows the proxy is there — it was configured to use it, or its traffic is being intercepted. The destination server does not know the real client exists.
The pattern: many clients, one proxy, many destinations.
Who deploys them: organisations wanting to control and observe outbound traffic from their own network. Schools, offices, hospitals, and government departments run forward proxies to filter content, enforce acceptable-use policies, scan for malware, cache commonly-fetched resources, and produce audit logs. Individuals use forward proxies to change the apparent origin of their requests.
Reverse proxies act for servers
A reverse proxy sits in front of servers and receives requests on their behalf. The client has no idea it is there — as far as the browser is concerned, the reverse proxy is the website. The backend servers never speak to the public internet directly.
The pattern: many clients, one proxy, a small number of backend servers you control.
Who deploys them: essentially everyone operating a website of any size. If you have visited a large site today, you went through a reverse proxy. They provide load balancing, caching, encryption handling, filtering, and a shield in front of infrastructure that should not be publicly reachable.
Holding the distinction straight
The memorable version: a forward proxy hides the client from the server; a reverse proxy hides the server from the client.
Or by ownership: with a forward proxy, you typically own the clients. With a reverse proxy, you own the servers.
The same software often does both. Nginx, Apache, and Squid can each be configured as either. The word "proxy" describes the mechanism; forward and reverse describe the deployment.
Forward proxies in detail
Explicit versus transparent
Explicit proxies require the client to be configured. Someone has entered the proxy's address into browser settings, applied it by group policy, or distributed it through a configuration file. The client is aware and cooperating.
Transparent proxies, also called intercepting proxies, need no client configuration. Network equipment redirects traffic to the proxy before it can leave, and the client has no idea. This is how large networks enforce filtering without touching thousands of devices.
The word "transparent" causes trouble here, so worth being precise: it refers to transparency to the client, not to anonymity. A transparent proxy is invisible to the user's configuration. It is not hiding anything from the destination server, and in the anonymity taxonomy below, "transparent" means something almost opposite to what people assume.
Configuration is usually distributed one of two ways. A PAC file (proxy auto-configuration) is a small JavaScript file returning which proxy to use for a given URL, allowing rules such as sending internal addresses direct and everything else through the proxy. WPAD automates discovery of that file via DHCP or DNS. WPAD is convenient and has a long history of security weaknesses, since a device that can answer the discovery query can nominate itself as your network's proxy. It is generally better to distribute the PAC file explicitly.
Anonymity levels
For forward proxies used to change apparent origin, three levels are conventionally distinguished, and they differ in which headers they add.
| Level | What the destination sees | Headers |
| Transparent | The proxy's IP, plus your real IP, plus the fact a proxy is in use | Adds X-Forwarded-For with your address and Via identifying itself |
| Anonymous | The proxy's IP, and that a proxy is in use, but not your address | Adds Via or similar but omits or masks your real address |
| Elite / high-anonymity | The proxy's IP only, with no indication a proxy is involved | Adds no forwarding headers |
Two practical notes. First, these categories are conventions rather than a standard, and a proxy's advertised level should be verified rather than trusted. Second, X-Forwarded-For is not a formal standard — RFC 7239 defines a Forwarded header intended to replace it, though the older header remains far more widely deployed.
That header matters more than it looks, and there is a security lesson in it covered later: any client can send an X-Forwarded-For header claiming any address, so an application trusting it uncritically can be lied to about where a request came from.
Protocol types
- HTTP proxies understand HTTP. They can read and modify requests, cache responses, filter by URL or content type, and inject or strip headers. They work only for HTTP traffic.
- HTTPS proxies handle encrypted traffic, either by tunnelling it or by intercepting it. Covered in the next section, because it is the most misunderstood area.
- SOCKS proxies operate at a lower level and are protocol-agnostic. SOCKS relays TCP connections without understanding what travels inside them, so it works for anything: email, file transfer, database connections, game traffic. SOCKS5 adds authentication, UDP support, and IPv6 over SOCKS4. Because it does not parse the application protocol, SOCKS cannot filter by content or cache — it is more flexible and less capable at the same time.
- FTP proxies handle file transfer, with control over uploads, downloads and virus scanning. Largely legacy.
- SMTP and mail proxies sit in the mail path for spam filtering, virus scanning, and policy enforcement.
- DNS proxies forward name resolution queries, commonly used for filtering at the domain level and for caching lookups.
Caching proxies
A caching forward proxy stores responses and serves subsequent identical requests from local storage. On a network where many people fetch the same resources, this reduces external bandwidth and improves response times, since a cached object is delivered at local network speed.
Caching proxies were transformative when bandwidth was scarce and expensive, and they remain useful in bandwidth-constrained or high-latency environments. Their general importance has declined for two reasons: bandwidth got cheaper, and most traffic is now encrypted, which prevents a proxy from caching content unless it is intercepting TLS.
Commercial proxy categories
A commercial market exists selling proxy access, mostly for automated data collection. The categories:
- Public / free proxies are open to anyone. Covered below; treat them as hazardous.
- Shared proxies are used by multiple customers simultaneously. Cheap, and you inherit whatever reputation your co-tenants create.
- Dedicated proxies are allocated to one customer. More expensive, predictable.
- Datacentre proxies originate from commercial hosting infrastructure. Fast and cheap, and readily identifiable as datacentre addresses, so sites wanting to block automated access block them easily.
- Residential proxies route through IP addresses assigned to home internet connections, which makes traffic look like ordinary consumer browsing.
- Mobile proxies use mobile carrier addresses, which are shared among many real users and therefore difficult to block without collateral damage.
- Rotating proxies change the outbound address automatically, per request or on a schedule.
A point of honesty about residential proxies, which the marketing around this category tends to omit. Those home IP addresses belong to real people. The networks are typically assembled by paying app developers to embed a software development kit that turns the user's device into an exit node, with the arrangement disclosed somewhere in a terms-of-service document the user did not read. Some providers operate more transparently than others, and some of these networks have been assembled through software the user would not have installed knowingly.
For a Canadian business, that raises questions worth asking before purchasing: whose connection is your traffic leaving from, did that person meaningfully agree, and are you comfortable with the answer. There is also a straightforward operational risk, in that a residential exit node is a stranger's device on a stranger's network.
Open proxies, and why free proxy lists are a bad idea
An open proxy accepts connections from anyone. Some are deliberate; most are misconfigured servers whose owners do not know they are relaying traffic.
Lists of free open proxies are easy to find and tempting. They are also, as a category, dangerous:
- You are handing your traffic to an unknown operator. Any traffic not end-to-end encrypted can be read and altered. Credentials, form contents, session cookies.
- Some exist specifically to harvest data. Running an open proxy is a low-effort way to collect other people's traffic.
- Content can be modified in transit. Injected advertising and injected scripts are both documented behaviours.
- The addresses are frequently already blocklisted, because they have been used for abuse.
- Reliability is nil. They appear and vanish without notice.
For any business use this is disqualifying, and for a Canadian business handling client information there is a compliance dimension: routing personal information through an unknown third party is difficult to reconcile with the safeguards and accountability obligations discussed later in this guide.
How proxies handle HTTPS, and what they can actually see
This is the section most guides get wrong, and getting it right changes how you think about the whole subject.
The claim to discard first
A proxy does not encrypt your traffic. You will read otherwise constantly. It is not true as a general statement.
Encryption on the web comes from TLS, the protocol behind HTTPS, and it operates between your browser and the destination server. If you visit an HTTPS site, your traffic is encrypted whether or not a proxy is involved. If you visit an HTTP site through a proxy, your traffic is not encrypted, and the proxy does not make it so — the connection from the proxy onward is exactly as exposed as it would have been.
A proxy can be a party to encryption in specific ways covered below. But "use a proxy to encrypt your connection" is a category error, and a costly one if it is the basis of a security decision.
Tunnelling: the CONNECT method
When your browser needs to reach an HTTPS site through an explicit proxy, it cannot simply hand over the request, because the request has not been encrypted yet and the whole point is that only the destination should decrypt it.
Instead the browser issues a CONNECT request, effectively asking the proxy to open a raw connection to a named host and port and then get out of the way. The proxy establishes that connection and afterwards relays bytes in both directions without interpreting them. The TLS handshake happens between your browser and the destination server, straight through the tunnel.
What the proxy can see in this arrangement:
- The destination hostname, from the CONNECT request itself and from the SNI field in the TLS handshake.
- The destination IP address and port.
- Timing, connection duration, and the volume of data transferred.
What it cannot see:
- The URL path. It knows you connected to com, not which page.
- Request and response bodies. Form contents, credentials, uploads, downloads.
- Cookies and headers.
This is why organisations that need genuine content inspection cannot rely on tunnelling. It also means the metadata a tunnelling proxy captures is still substantial: a log of every hostname each employee connected to, with timing, is a revealing dataset even without any content.
Interception: TLS inspection with an internal certificate authority
Where an organisation genuinely needs to inspect encrypted content — for malware scanning, data loss prevention, or regulatory monitoring — the technique is TLS interception, sometimes called SSL inspection or a man-in-the-middle proxy.
It works like this. The organisation generates its own certificate authority and installs that CA certificate as trusted on every managed device. When a browser connects to an HTTPS site, the proxy intercepts, presents a certificate for that site which it generates on the fly and signs with the internal CA, and separately establishes its own TLS connection onward to the real server. Two encrypted connections exist, and the proxy sits between them holding both sets of keys, seeing everything in plaintext.
The browser does not complain, because the certificate is signed by an authority the device has been told to trust. On an unmanaged device it fails loudly, which is the intended behaviour.
Several things follow, and they are worth stating plainly:
- The proxy operator can read everything. Every URL, every form submission, every password typed into a web page, every file transferred. This is not a side effect; it is the purpose.
- The security guarantee of HTTPS is deliberately broken for those connections, and replaced with trust in the organisation running the proxy.
- Certificate pinning breaks it. Applications that pin expected certificates will refuse to connect. Banking apps and various software update mechanisms behave this way, which is why intercepting proxies maintain bypass lists.
- Interception is a security risk in its own right. The proxy holds a CA key trusted by every device in the organisation. Compromise of that key is severe, and interception appliances have historically had implementation weaknesses of their own.
- There is a Canadian privacy dimension. Inspecting employee traffic that includes personal communications engages workplace privacy expectations. Canadian privacy law and jurisprudence generally require employers to have a legitimate purpose, to limit collection proportionately, and to be transparent about monitoring. The Office of the Privacy Commissioner has published guidance on workplace privacy. Deploying TLS inspection without a clear, communicated policy is a legal and employee-relations exposure, not merely a technical decision.
SNI, and what changed in 2026
Historically the one piece of a TLS connection that remained readable to any observer on the path was the Server Name Indication field, which tells the server which hostname the client wants — necessary when many sites share an IP address. SNI is sent before encryption is established, so it was visible in the clear.
That is a large part of why hostname-level filtering worked at all without full interception. A proxy or firewall could read the SNI and make a decision.
Encrypted Client Hello (ECH) changes this, and it moved from long-running draft to published standard as RFC 9849 in March 2026. ECH encrypts the ClientHello, including SNI and the protocol list, so a network observer sees a connection to a shared placeholder hostname rather than the actual destination. Recent versions of Chrome, Edge and Firefox support it, and CDN and hosting platforms have been enabling it.
For anyone operating a filtering proxy, the practical implication is that SNI-based decisions degrade as ECH deployment grows. There has been active debate at the IETF about exactly this, with network operators and security vendors documenting the loss of visibility for malware detection, parental controls and content filtering, and proponents pointing to the privacy gain. The direction of travel is toward less on-path visibility, which pushes organisations needing content inspection toward endpoint agents and full interception rather than passive network observation.
If you are evaluating a filtering solution now, this is a question worth asking the vendor.
Reverse proxies: what they do for a website
If you operate a website, this is the half of the subject that touches your infrastructure directly. A reverse proxy is standard practice rather than an advanced technique, and understanding what it does explains a lot about how websites are actually assembled.
Load balancing
The best-known function. Requests arrive at the reverse proxy, which distributes them across several backend servers.
Common distribution methods:
- Round robin, cycling through servers in order. Simple, and assumes requests cost roughly the same.
- Weighted round robin, sending proportionally more traffic to more capable servers.
- Least connections, favouring whichever backend is currently handling fewest. Better where request duration varies.
- IP hash, mapping a client consistently to the same backend, which matters when session state is held locally rather than shared.
- Least response time, using observed backend latency.
Alongside distribution sits health checking. The proxy tests backends periodically and removes failing ones from rotation, returning them when they recover. This is what allows a server to fail without the site going down, and it is the difference between redundancy on paper and redundancy in practice.
Caching
A reverse proxy can store responses and serve them itself. For content that does not change per visitor, this is dramatic: the backend generates the page once and the proxy serves it thousands of times without the application, the database, or the interpreter being involved.
For a WordPress site, the difference between a cached and uncached page view is typically the difference between a few milliseconds and a few hundred. That is a direct improvement in time to first byte, which sets the floor under every other performance metric your site is measured on.
TLS termination
The reverse proxy holds the certificate and handles the TLS handshake, then communicates with backends over plain HTTP within a trusted network, or re-encrypts if the network is not trusted.
The benefits are practical: certificates live in one place rather than on every backend, renewal is a single operation, and the cryptographic work is concentrated where it can be optimised. Where a certificate is installed and renewed is one of the more common sources of confusion when a site sits behind a proxy, and it is worth knowing which layer owns it before a renewal is due.
Where termination happens also determines where your traffic is decrypted, which is a point returned to in the Canadian section, because it has implications many businesses have not considered.
Web application firewalling and filtering
Because the reverse proxy sees every request before the application does, it is the natural place to inspect and reject malicious traffic — injection attempts, known exploit patterns, malformed requests, traffic from blocklisted sources. Blocking at the proxy means the application never processes the request and never spends resources on it.
Rate limiting and abuse control
The proxy can cap requests per client, per endpoint, or per time window. This protects login endpoints from credential stuffing, protects expensive operations like search from being hammered, and absorbs a portion of what a small denial-of-service attempt would otherwise deliver to your application.
Concealing your infrastructure
Clients connect to the proxy and nothing else. Backend addresses, server software, operating system versions, and internal topology are not exposed. An attacker who cannot address your application servers directly has a smaller surface to work with.
Compression, protocol handling, and rewriting
Reverse proxies commonly compress responses, handle newer protocol versions on behalf of backends that do not speak them, rewrite URLs and headers, and serve multiple applications under one domain by routing different paths to different backends.
Deployment routing
Because the proxy decides which backend receives a request, it enables deployment patterns that would otherwise be difficult: sending a small percentage of traffic to a new version to test it, or switching an entire environment over at once with the ability to switch back.
The software
Common reverse proxy software includes Nginx, widely used and efficient at concurrent connections; Apache HTTP Server, via its proxy modules; HAProxy, specialised in load balancing and health checking; Caddy, which handles certificate provisioning automatically; Traefik, oriented to container environments; and Envoy, common in service mesh architectures.
Running any of these means having control over the server, which shared hosting does not generally provide. It is one of the practical reasons businesses outgrow shared environments: not that they need more raw capacity, but that they need to configure the layer in front of the application. VPS hosting with root access is usually where that becomes possible, and dedicated server hosting where resource isolation matters as well as control.
Layer 4 versus layer 7
A distinction worth knowing when reading documentation.
Layer 4 proxying operates on TCP connections. The proxy forwards connections without interpreting their contents. It is fast, protocol-agnostic, and works for encrypted traffic without decrypting it — but it cannot route by URL, cache, or inspect content.
Layer 7 proxying operates on the application protocol. The proxy parses HTTP, so it can route by path or header, cache, compress, rewrite, and inspect. It requires understanding the protocol, and for encrypted traffic it requires terminating TLS.
Most website reverse proxies operate at layer 7 precisely because those capabilities are the point.
CDNs are distributed reverse proxies
A content delivery network is a large fleet of reverse proxies in data centres worldwide, operated as a service. A request goes to the nearest edge node, which serves cached content directly or fetches from your origin server and caches the result.
The benefit is geographic. A visitor in Halifax fetching from an edge node in Montreal experiences a shorter round trip than one fetching from Vancouver, and distance imposes a latency floor no software can remove.
Two things about CDNs are worth being clear on, because they are frequently misunderstood.
A CDN does not replace your hosting. The origin still exists, still serves anything uncacheable, and still determines how fast dynamic responses are generated. A CDN in front of a slow origin produces a site that is fast for cached assets and slow for everything else.
Where the edge node is determines where your traffic is handled. Global CDNs route to whichever node is nearest, which for a Canadian visitor may or may not be in Canada. This matters, and the next section explains why.
Benefits, organised by who actually gets them
Most articles present a single list of proxy benefits, which obscures the fact that different proxies benefit different parties. Sorted properly:
For the person or device making requests (forward proxy):
- The destination does not learn the requester's address.
- Cached content arrives faster and costs no external bandwidth.
- Malicious sites can be blocked before the device reaches them.
- Requests appear to originate from the proxy's location.
For an organisation operating a network (forward proxy):
- Acceptable-use policy enforced at one point rather than per device.
- Complete logs of outbound activity, for auditing and investigation.
- Bandwidth saved through caching.
- Malware and phishing filtered centrally, covering devices that lack their own protection.
- Data loss prevention, where interception is in use.
For an organisation operating a website (reverse proxy):
- Traffic distributed across servers, with capacity added without client-side changes.
- Individual server failure without site failure.
- Substantially faster responses for cacheable content, improving time to first byte.
- Certificates managed in one place.
- Malicious requests rejected before reaching the application.
- Rate limiting against abuse and brute-force attempts.
- Backend infrastructure not publicly addressable.
- Deployment patterns that reduce release risk.
Only that third group is directly relevant to most small businesses, which is worth knowing when reading proxy content aimed at security professionals or data-scraping operations.
Limitations, risks, and how proxies fail
A guide that lists only benefits is not useful. Here is the other half.
A new single point of failure
Every request passes through the proxy, so if the proxy is down, everything is down — including backends that are perfectly healthy. A reverse proxy deployed for reliability, without redundancy of its own, can reduce overall availability rather than improve it.
Added latency
Each proxy hop adds work: a connection to establish, a request to parse, a response to relay. Usually a small cost, and usually repaid several times over by caching. But it is a real cost, and it grows when the proxy is geographically distant from either the client or the origin. Routing Canadian visitors through a proxy in another country to reach a server in Canada adds two long trips to every request.
Encrypted traffic is opaque unless intercepted
A filtering proxy that is not performing TLS interception cannot inspect content. As covered, it sees hostnames and metadata. Organisations sometimes believe their filtering is more comprehensive than it is, and ECH deployment is reducing even the hostname visibility.
Configuration mistakes with real consequences
Reverse proxies sit at the boundary between the internet and your application, which makes their misconfigurations serious.
- Open relay. A forward proxy left accessible from the internet will be found and used for abuse, and your address will end up on blocklists.
- Server-side request forgery. A proxy or application that fetches URLs supplied by users can be induced to request internal addresses, including cloud metadata endpoints, from a position of trust inside your network.
- Host header injection. An application that trusts the Host header to construct URLs can be manipulated into generating links pointing at an attacker's domain, which is a common mechanism for password reset poisoning.
- HTTP request smuggling. Where a proxy and a backend disagree about where one request ends and the next begins, an attacker can hide a second request inside the first. The consequences range from bypassing access controls to poisoning responses served to other users. This class of bug arises specifically from having two HTTP implementations in sequence, which is to say it is a proxy-specific risk.
- Cache poisoning. If the proxy caches a response keyed on inputs an attacker can influence, a malicious response can be served to subsequent visitors.
Trusting forwarded headers
This deserves separate mention because the mistake is so common.
When a reverse proxy sits in front of your application, the application's connection comes from the proxy, so every request appears to originate from the proxy's address. To recover the real client address, proxies add a header — conventionally X-Forwarded-For, or the standardised Forwarded from RFC 7239.
The problem: any client can send that header with any value. If your application reads it uncritically, an attacker can claim to be any address they like. That defeats IP-based rate limiting, corrupts your analytics and logs, can bypass IP allowlists, and can poison abuse-detection systems.
The correct handling is to configure your application to trust the header only when the connection comes from a proxy you actually operate, and to use only the value your proxy appended rather than any values a client may have supplied. Nginx has set_real_ip_from and real_ip_header for this; most application frameworks have an equivalent trusted-proxy setting. It is a five-minute configuration that is frequently skipped, and until it is done your logs are not evidence of anything.
Gateway errors
If you have seen a 502 Bad Gateway or 504 Gateway Timeout, you have seen a reverse proxy reporting a problem with something behind it. A 502 means the proxy got an invalid response from the backend; a 504 means the backend did not respond in time. The proxy is working — it is telling you the layer behind it is not.
This is worth recognising, because these errors are frequently misdiagnosed as problems with the proxy or CDN when the actual fault is a crashed application process, an exhausted connection pool, or a database that has stopped responding. Our guide on how to fix a 502 Bad Gateway error walks through the diagnostic sequence.
Operational complexity
Every layer added is a layer to configure, monitor, patch, and debug. Caching in particular introduces a whole class of problems that did not previously exist: stale content, incorrectly cached personalised pages, and the recurring question of why a change is not showing up. These are manageable, and they are not free.
What Canadian businesses should think about specifically
Four considerations that general proxy guidance, most of it written for American or international audiences, does not address.
Where TLS terminates is where your traffic is decrypted
This is the most consequential point in this guide and the one least discussed anywhere.
A common architecture for a Canadian business: hosting on Canadian servers, with a global CDN or proxy service in front for performance and security. Entirely sensible, and widely recommended.
What it means mechanically is that the CDN terminates TLS at whichever edge node is nearest the visitor. Your traffic is decrypted there, processed there, and re-encrypted or forwarded from there. If that node is in Seattle, Chicago or Ashburn — all plausible for a Canadian visitor depending on routing — then that is where the decryption happens, regardless of where your origin server sits.
Why this matters: a number of Canadian businesses tell clients their data stays in Canada, on the basis of Canadian hosting. If a global edge network sits in front, that statement needs qualifying. The stored data may well be in Canada. The traffic in transit, including form submissions, login credentials, and whatever else moves through those requests, is being decrypted wherever the edge node is.
This is not an argument against using a CDN. It is an argument for knowing what you have deployed and describing it accurately:
- If you make data residency commitments to clients, in contracts, in a privacy policy, or in a procurement response, check where your edge terminates. Some providers offer region-restricted configurations; some do not.
- If you serve regulated sectors — healthcare, legal, financial services, education, public sector — this question will eventually be asked by someone doing due diligence, and "our hosting is in Canada" may not be a sufficient answer.
- If your priority is a genuinely Canadian path, hosting close to your audience without a global edge layer in front can be the simpler architecture. Serving Canadian visitors from Canadian data centres in Vancouver and Toronto covers both ends of the population distribution with short round trips, and keeps the question of where decryption happens straightforward to answer.
PIPEDA and routing personal information through intermediaries
The Personal Information Protection and Electronic Documents Act governs how private-sector organisations in Canada handle personal information in commercial activity, with substantially similar provincial legislation applying in Quebec, British Columbia and Alberta.
A proxy in your traffic path is a party through which personal information flows. Three obligations become relevant:
Safeguards. You must protect personal information with measures appropriate to its sensitivity. Routing client data through an open proxy, a free proxy list, or a service whose operator you cannot identify is difficult to defend as an appropriate safeguard.
Accountability for third-party processing. Transferring personal information to a third party for processing is permitted, but you remain accountable for it. Contracting with a proxy or CDN provider does not transfer the responsibility, and you are expected to use contractual and other means to ensure comparable protection.
Transparency. People are entitled to understand what happens to their information. If it routes through third-party infrastructure, potentially outside Canada, your privacy policy should say so rather than leaving the impression everything is handled in-house.
Quebec's Law 25 raises the bar further for organisations with Quebec customers, including requirements around assessments before transferring personal information outside the province.
Latency and proxy placement for a Canadian audience
Canada is geographically enormous and its population is concentrated in a few places. Distance costs time on every request, permanently, and no software optimisation removes it.
For a business whose customers are Canadian, the sensible arrangement is short paths: origin infrastructure near the population you serve, and any proxy layer either close to your visitors or close to your origin, not scattered somewhere unrelated. Adding a proxy hop in a distant country to reach a Canadian server means every request crosses the continent twice for no benefit.
This connects to how your site is measured. Time to first byte sets the floor under Largest Contentful Paint, so a badly-placed proxy shows up directly in your Core Web Vitals field data — which is a page experience signal — and in whether crawlers get quick, consistent responses when they fetch your pages. Infrastructure placement is not purely an engineering preference; it is visible in your performance reporting.
Employee monitoring and workplace privacy
If you deploy a forward proxy that logs or inspects employee traffic, you are collecting information about identifiable individuals in a Canadian workplace.
The general expectation under Canadian privacy law and jurisprudence is that monitoring should serve a legitimate business purpose, be proportionate to that purpose, be no more intrusive than necessary, and be disclosed to the people affected. Employees do retain some privacy expectation on work systems, and it is not eliminated by ownership of the equipment.
Practically: have a written policy, communicate it, collect the minimum you need, set a retention period and honour it, and restrict who can access the logs. If you are performing TLS interception, be specific about it, because the collection involved is far broader than most employees would assume. Provincial requirements vary — Quebec, British Columbia and Alberta each have their own regimes — so a business operating across provinces should check rather than assume a single standard applies.
Five situations, and what proxies do in each
A 40-person office in Winnipeg
Deployment: a forward proxy for outbound traffic.
Purpose: blocking malware and phishing domains, enforcing acceptable use, producing logs for incident investigation.
What to get right: decide deliberately whether to intercept TLS. Filtering without it gives you hostname-level control and no content visibility, which is a legitimate choice with lower privacy exposure. Filtering with it gives you full visibility and a substantially larger obligation. Write the policy first; the technology follows from it.
An online store shipping across Canada
Deployment: a reverse proxy in front of the application, likely with a CDN.
Purpose: caching product and category pages, distributing traffic during promotional peaks, filtering malicious requests, terminating TLS.
What to get right: cache rules that never cache a logged-in customer's cart or account pages. Miscached personalised content is a genuine data exposure, not just a bug. Also confirm where TLS terminates if you make residency claims, and configure trusted-proxy handling so fraud checks see real client addresses rather than the proxy's.
A design agency in Toronto running client sites
Deployment: a reverse proxy routing by hostname to separate backends.
Purpose: hosting many client sites and staging environments behind one entry point, with per-site rules, IP restrictions on staging, and centralised certificate management.
What to get right: hostname routing rules that cannot leak between clients, and staging environments that are both access-restricted and excluded from indexing. Certificate automation matters at this scale — manual renewal across dozens of domains fails eventually.
A trades business in Calgary with one WordPress site
Deployment: most likely none of their own, and that is the correct answer.
Purpose: not applicable. A single low-traffic site does not need load balancing, and page caching at the application or host level delivers most of the performance benefit without a separate proxy layer.
What to get right: recognising that this article's reverse proxy section is not a to-do list. If managed WordPress hosting is handling caching and certificates, the job is done. Complexity added without need is complexity that will break at an inconvenient moment.
A clinic in Halifax handling health information
Deployment: a reverse proxy with a web application firewall; possibly no third-party edge network.
Purpose: filtering malicious traffic before it reaches an application holding sensitive data, rate limiting the patient portal, keeping backend systems unreachable from the internet.
What to get right: this is the case where the TLS termination question is decisive. Health information attracts both PIPEDA and provincial health-information legislation, and a global edge network decrypting patient portal traffic outside Canada is a question you want answered before a regulator or a client asks it. Keeping the path inside Canada is the simpler position to defend.
Common misconceptions, corrected
A quick reference, and the fastest way to check whether a proxy article you are reading is reliable.
| Common claim | What is actually true |
| "A proxy encrypts your traffic" | It does not. Encryption comes from TLS, between browser and destination. A proxy can terminate or intercept TLS, but it does not add encryption where none existed |
| "A proxy makes you anonymous" | It hides you from the destination and reveals you to the proxy operator. Anonymity depends entirely on who runs it and what they log |
| "Proxies and VPNs are basically the same" | A VPN operates at the network layer, covers all traffic, and encrypts by definition. A proxy is typically per-application and does not |
| "Transparent proxy means it hides you" | "Transparent" means no client configuration is required. In the anonymity taxonomy, transparent proxies pass your real address along |
| "A reverse proxy is just a load balancer" | Load balancing is one function. Caching, TLS termination, filtering, rate limiting and origin concealment are others |
| "Free proxies are fine for light use" | You are giving an unidentified operator the ability to read and modify anything not end-to-end encrypted |
| "A CDN means my site is fast" | Cacheable content becomes fast. Dynamic responses still depend on your origin |
| "My hosting is in Canada, so my data stays in Canada" | Stored data may. Traffic decrypted at a foreign edge node does not |
| "The proxy caused my 502 error" | A 502 is the proxy correctly reporting that the backend behind it returned an invalid response |
| "Adding a reverse proxy improves reliability" | Only with redundancy of its own. Otherwise it is a new single point of failure |
| "X-Forwarded-For tells me the real client IP" | Only if you validate it. Any client can forge that header |
| "Residential proxies are just faster proxies" | They route through real people's home connections, often assembled through consent arrangements worth examining before you buy |
Glossary
Backend / origin — the server actually generating responses, behind the proxy.
CONNECT — the HTTP method a client uses to ask a proxy to open a tunnel for encrypted traffic.
Elite proxy — a forward proxy adding no headers revealing that a proxy is in use.
Forward proxy — a proxy acting on behalf of clients, making outbound requests for them.
Health check — a periodic test by which a proxy determines whether a backend is able to serve traffic.
Layer 4 / Layer 7 — proxying at the TCP connection level versus the application protocol level.
Open proxy — a proxy accepting connections from anyone, usually through misconfiguration.
PAC file — a configuration file returning which proxy a client should use for a given URL.
Reverse proxy — a proxy acting on behalf of servers, receiving inbound requests for them.
SNI — Server Name Indication, the TLS field identifying the requested hostname; historically sent unencrypted, now encryptable via ECH.
SOCKS — a protocol-agnostic proxy standard relaying TCP connections without interpreting them.
TLS termination — the point at which encryption is decrypted, typically at the proxy rather than the backend.
Transparent proxy — a proxy intercepting traffic without client configuration.
Upstream — in proxy configuration, the backend server or pool a request is forwarded to.
WAF — web application firewall, inspecting and filtering HTTP requests for malicious patterns.
X-Forwarded-For — a conventional header carrying the original client address through a proxy; forgeable unless validated.
If you are deploying one: what to check
Not a tutorial, but the checklist worth running.
For a reverse proxy in front of a website:
- Confirm the proxy layer is redundant, or accept that it is a single point of failure.
- Configure health checks that test something meaningful, not merely whether the port is open.
- Set cache rules explicitly, and verify that no authenticated or personalised response is ever cached.
- Establish which layer owns TLS certificates and how renewal happens. Test a renewal before one is urgent.
- Configure trusted-proxy handling so your application reads real client addresses and ignores forged headers.
- Make sure backends are not reachable directly from the internet, or the proxy's protections can be bypassed.
- Confirm timeouts are consistent between proxy and backend, since mismatches produce intermittent 504s.
- Log at the proxy, and make sure those logs carry the real client address.
- Verify your proxy and backend HTTP implementations agree on request parsing, which is the defence against request smuggling.
- Check where TLS terminates geographically, and whether that matches what you tell clients.
For a forward proxy on a business network:
- Write the acceptable-use and monitoring policy before deploying, and communicate it.
- Decide deliberately about TLS interception, weighing visibility against privacy obligation.
- Never expose it to the internet.
- Set log retention and honour it. Indefinite retention of employee browsing is an unnecessary liability.
- Restrict who can access logs, and log those accesses.
- Plan for certificate pinning breaking specific applications if intercepting.
- Distribute configuration through managed policy rather than relying on WPAD discovery.
- Consider how ECH deployment will affect hostname-based filtering over the next few years.
Where this is heading
Cautious forecasting, marked as such.
On-path visibility is declining. Encrypted DNS, and now ECH as a published standard, are steadily removing the metadata that network-level filtering relied on. The likely consequence is a shift toward endpoint agents and full interception for organisations that genuinely need content visibility, and reduced effectiveness for everyone relying on passive observation.
Reverse proxies are becoming assumed infrastructure. The direction over the last decade has been toward the layer in front of the application doing more: routing, authentication, rate limiting, observability. That trend has no obvious reason to reverse.
Data residency questions are getting sharper, not softer. Between provincial privacy reform in Canada and procurement expectations in regulated sectors, "where exactly does this traffic go" is a question being asked more often and answered more carefully. Knowing where your edge terminates is moving from a technical detail to a commercial one.
The proxy market for automated data collection faces pressure. Residential proxy networks depend on consent arrangements that are attracting increasing attention from privacy regulators and platform operators. How that resolves is genuinely uncertain.
11. FAQ
What is a proxy server in simple terms?
A proxy server is a computer that makes requests on behalf of something else. Instead of your device talking directly to a website, it talks to the proxy, and the proxy talks to the website and relays the answer back. Because the proxy sits in the middle, it can hide who made the request, filter or log what passes through, and store copies of responses to serve them faster next time.
What is the difference between a forward proxy and a reverse proxy?
Direction and whose behalf it acts on. A forward proxy sits in front of clients and makes outbound requests for them, hiding the client from the destination server — typical on office and school networks. A reverse proxy sits in front of servers and receives inbound requests for them, hiding the server from the client — used by essentially every website of any size. The shorthand: a forward proxy hides the client, a reverse proxy hides the server.
Does a proxy server encrypt my traffic?
Generally no, and this is the most common misconception about proxies. Encryption on the web comes from TLS, which operates between your browser and the destination site. An HTTPS site is encrypted whether or not a proxy is involved, and an HTTP site is not encrypted just because you added one. A proxy can terminate TLS, or intercept it, but it does not create encryption that was not otherwise there.
Is a proxy the same as a VPN?
No. A VPN operates at the network layer, so every application's traffic goes through it, and it encrypts that traffic by definition. A proxy is usually configured per application or protocol, so your browser might use it while your email client does not, and it does not inherently encrypt. Both share one important limitation: whoever runs the intermediary can see whatever is not end-to-end encrypted.
Can a proxy see my passwords?
If the connection is HTTP, yes, along with everything else. If the connection is HTTPS and the proxy is tunnelling, no — it sees the hostname and connection metadata only. If the proxy is performing TLS interception with a certificate authority your device has been configured to trust, then yes, it can see everything in plaintext including credentials. This is how corporate content inspection works, and it is why installing an organisation's root certificate on a device is a significant grant of access.
Are free proxy servers safe to use?
No, for business purposes. A free or open proxy means an unidentified operator can read and modify anything you send that is not end-to-end encrypted. Some exist specifically to harvest traffic, injected advertising and scripts are documented behaviours, the addresses are often already blocklisted, and reliability is unpredictable. For a Canadian business handling client information there is also a compliance problem, since routing personal information through an unknown third party is hard to defend as an appropriate safeguard under PIPEDA.
Do I need a proxy server for my small business website?
Probably not a separate one you configure yourself. A single low-traffic site does not need load balancing, and caching at the application or hosting level delivers most of the performance benefit. Reverse proxies become genuinely worthwhile when you outgrow one server, need to distribute traffic, want a web application firewall in front of your application, or need to route several sites through one entry point. Managed hosting often provides the useful parts already.
Does using a reverse proxy or CDN help SEO?
Indirectly, through performance. Faster time to first byte and better Core Web Vitals field data are page experience signals, and consistent quick responses help crawlers fetch your pages reliably. There is no direct ranking benefit from having a proxy. And it cuts both ways: a poorly configured proxy that adds latency, caches wrongly, or returns intermittent gateway errors will hurt more than the absence of one.
What does a 502 Bad Gateway error mean?
It means a reverse proxy received an invalid response from the server behind it. The proxy is working correctly and reporting a problem further back — often a crashed application process, an exhausted connection pool, or an unresponsive database. A 504 Gateway Timeout is the related case where the backend did not respond in time. Both point at the backend rather than the proxy itself.
Why does my website show the proxy's IP address instead of the visitor's?
Because with a reverse proxy in place, the connection your application receives genuinely comes from the proxy. Proxies pass the original address in a header, conventionally X-Forwarded-For. Your application needs to be configured to read it — but only when the connection comes from a proxy you operate, because any client can forge that header. Nginx uses set_real_ip_from and real_ip_header; most frameworks have a trusted-proxy setting.
If my hosting is in Canada, does my data stay in Canada?
Your stored data does. Your traffic may not. If a global CDN or proxy service sits in front of your Canadian hosting, TLS is terminated at whichever edge node is nearest the visitor, and that node may be outside Canada — meaning that is where your traffic is decrypted. If you make data residency commitments in contracts, privacy policies or procurement responses, this is worth verifying rather than assuming.
What is Encrypted Client Hello and why does it matter for proxies?
ECH encrypts the part of the TLS handshake that previously revealed which hostname a client was connecting to. Published as RFC 9849 in March 2026 and supported by recent Chrome, Edge and Firefox versions, it means network observers see a connection to a shared placeholder name rather than the real destination. For filtering proxies that relied on reading that field to make decisions, this reduces visibility, and it is pushing organisations that need content inspection toward endpoint software or full TLS interception.
Key Takeaways
- A proxy server is an intermediary that makes requests on behalf of something else. Everything else follows from that: hiding the requester, providing a control point, and enabling caching.
- Forward proxies act for clients; reverse proxies act for servers. A forward proxy hides the client from the destination. A reverse proxy hides the server from the client. Nearly all confusion about proxies dissolves at this distinction.
- Proxies do not encrypt traffic. Encryption comes from TLS. A proxy can terminate or intercept it, not create it.
- A tunnelling proxy sees hostnames and metadata; an intercepting proxy sees everything. TLS interception requires installing a trusted certificate authority on managed devices and is a substantial grant of visibility.
- Free and open proxies mean handing your traffic to an unidentified operator. Not viable for business use, and difficult to reconcile with PIPEDA safeguards.
- Reverse proxies do far more than load balancing — caching, TLS termination, web application firewalling, rate limiting, origin concealment, and deployment routing.
- Never trust `X-Forwarded-For` without validating it. Any client can forge it, which breaks rate limiting, allowlists and logs.
- Where TLS terminates is where your traffic is decrypted. Canadian hosting behind a global edge network does not mean traffic stays in Canada.
- A proxy without redundancy is a new single point of failure, and can lower availability rather than raise it.
- Most single-site small businesses do not need to deploy a proxy themselves. Recognising that is as useful as knowing how they work.
Conclusion
The word "proxy" covers more ground than one term reasonably should, which is why the subject feels harder than it is. Once you separate the two directions — acting for clients, or acting for servers — the rest of the taxonomy arranges itself, and the exotic-sounding categories turn out to be variations on configuration and commercial packaging.
What is worth carrying away is the corrective. A proxy does not encrypt anything by itself. It does not make you anonymous; it changes who can observe you. It is not interchangeable with a VPN. And in the reverse direction, it is not merely a load balancer, but a layer that shapes performance, security, and reliability in ways that show up directly in how fast your site responds and how reliably it stays up.
For a Canadian business the practical questions are narrower than the literature suggests. If you run a single site, you probably need caching and a certificate, both of which good hosting provides, and nothing else in this guide is a task on your list. If you have outgrown one server, or need filtering in front of an application holding sensitive data, or are running multiple sites behind one entry point, then a reverse proxy is the standard answer and this guide describes what it does.
And whatever the scale, one question is worth answering deliberately rather than by accident: where in the world your traffic is being decrypted, and whether that matches what you have told the people who trusted you with it.
The layer in front of your application is where a lot of performance and security actually lives.
If you have reached the point where you need to configure it — a reverse proxy for caching or load balancing, a web application firewall in front of an application holding sensitive data, several sites routed through one entry point, or control over where your traffic terminates — that requires a hosting environment that gives you the access to do it.
Shared hosting generally does not. VPS hosting with root access is usually where configuring Nginx, Apache or HAProxy as a reverse proxy becomes possible, and where you can set outbound and inbound behaviour rather than accepting defaults. Where resource isolation matters as much as control, dedicated server hosting removes the co-tenancy question entirely.
If you are running a single WordPress site and the reverse proxy section read like someone else's problem, that is the right conclusion. Managed WordPress hosting handles the caching and certificate layer for you, which is most of the practical benefit without the configuration surface. And if any part of your site is still reachable over plain HTTP, an SSL certificate with proper server-level redirection is the first thing to fix, before anything else in this guide.
On the residency question: 4GoodHosting serves Canadian visitors from data centres in Vancouver and Toronto, which keeps round trips short for a Canadian audience and makes "where is our traffic handled" a question with a simple answer. If you are weighing that against a global edge network, we are happy to talk through the trade-off honestly, including the cases where the edge network is the better choice.
Not sure which applies to you? Get in touch and we will look at your setup with you.